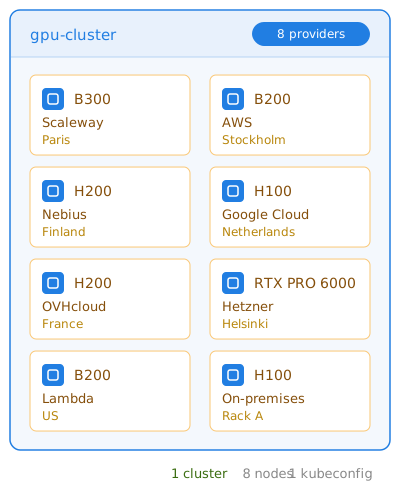
GPUs are scarce, and no single cloud has enough. Cloudfleet pools GPU capacity from AWS, Google Cloud, Azure, Hetzner, OVHcloud, Scaleway, Lambda, Nebius and your own data center into one managed Kubernetes cluster, and our team helps you procure the GPUs you cannot find.
A sample of the GPU instances and servers that cloud providers list today, from single L4 cards for inference to 8-GPU HGX nodes for training. Every row can join the same Cloudfleet cluster, through node auto-provisioning, the Cloudfleet API, or Terraform. Mix and match providers in one cluster and let your workloads land wherever the GPUs are.
Provider
GPU
Instance or server
GPUs per node
Interconnect
Where
List price
Scaleway
B300 288 GB
B300-SXM-8-288G
8
SXM
Paris
€7.50/h
Verda
B300 268 GB
B300 SXM6
1 to 8
InfiniBand on clusters
Helsinki
$11.57/h
Crusoe
B300 288 GB
b300-288gb-sxm-ib.8x
8
InfiniBand 6.4 Tbps per node
Iceland
$8.96/h
Nebius
B300 288 GB
8x B300
1 or 8
InfiniBand 800 Gbps
Paris, UK
$9.50/h
AWS
B300 268 GB
p6-b300.48xlarge
8
EFA 6.4 Tbps
US (London through Capacity Blocks)
$17.80/h
Together AI
B300 270 GB
HGX B300
8
InfiniBand
US
$9.99/h
Civo
B300 288 GB
8 x NVIDIA B300
8
NVLink 5, ConnectX-8 800 Gb/s
Global
$7.49/h
Hyperstack
B300 288 GB
n3-B300-SXM6x8
8
SXM6
Canada
$7.40/h
FPT AI Factory
B300 288 GB
B300 SXM
1 to 8
NVLink 5
Southeast Asia
$6.99/h
CoreWeave
B300 270 GB
b300-8x
8
InfiniBand XDR 800 Gb
US
On request
Gcore
B300 288 GB
8×B300 SXM bare metal
8
Europe, global
On request
IREN
B300 288 GB
NVIDIA B300
8
InfiniBand 3.2 Tb/s
Canada, US, Spain, Australia
On request
Voltage Park
B300 288 GB
HGX B300
8
NVLink, 1.6 TB/s network
US
Contract
Lambda
B300
HGX B300 Supercluster
8
InfiniBand
US
Reserved
Verda
GB300 288 GB
GB300 SXM6
1, clusters up to 144
NVLink 5, InfiniBand
Finland
$13.31/h
CoreWeave
GB300 279 GB
GB300 NVL72
4 per instance, NVL72
Quantum-X InfiniBand
Canada, US
On request
Crusoe
GB300 288 GB
GB300 NVL72
NVL72
NVLink, InfiniBand
Iceland
On request
Gcore
GB300 288 GB
72×GB300 NVL72
72
NVLink 130 TB/s, InfiniBand
Europe, global
On request
AWS
B200 180 GB
p6-b200.48xlarge
8
NVLink, EFA 3.2 Tbps
Stockholm, Paris, US
$14.24/h
Google Cloud
B200 180 GB
a4-highgpu-8g
8
NVLink, RoCE
Netherlands, Belgium, Finland
$8.06/h (Flex-start)
CoreWeave
B200 180 GB
HGX B200
8
InfiniBand
Spain, US
$8.60/h
Verda
B200 180 GB
B200 SXM6
1 to 8
InfiniBand on clusters
Finland
$9.05/h
Together AI
B200 180 GB
HGX B200
8
InfiniBand 3.2 Tbps
US
$8.19/h
Lambda
B200 180 GB
B200 SXM6
1 to 8
NVLink
US
from $6.69/h
Hyperstack
B200 180 GB
n3-B200-SXM6x8
8
SXM6
Canada
$6.00/h
Civo
B200 180 GB
8 x NVIDIA B200
8
Global
$4.49/h (12-month commitment)
Crusoe
B200 180 GB
b200-180gb-sxm-ib-8x
8
InfiniBand 3.2 Tbps
Iceland, Norway, US
On request
Azure
GB200 192 GB
ND128isr_NDR_GB200_v6
4 per VM, NVL72
NVLink, InfiniBand 400 Gb
Germany, Italy, Spain, UK
$27.04/h
CoreWeave
GB200 186 GB
GB200 NVL72
4 per instance, NVL72
NVLink, InfiniBand
Canada, US
$10.50/h
Crusoe
GB200 186 GB
gb200-186gb-nvl-4x
4 per instance
InfiniBand 1.6 Tbps
Iceland
On request
AWS
H200 141 GB
p5en.48xlarge
8
NVLink, EFA 3.2 Tbps
Stockholm, Spain, US
$7.91/h
Azure
H200 141 GB
ND96isr_H200_v5
8
NVLink, InfiniBand 400 Gb per GPU
11 EU and UK regions
$10.60/h
CoreWeave
H200 141 GB
HGX H200
8
InfiniBand
Barcelona, US
$6.31/h
Verda
H200 141 GB
H200 SXM5
1 to 8
InfiniBand on clusters
Finland
$6.38/h
Together AI
H200 141 GB
HGX H200
8
InfiniBand 3.2 Tbps
US
$5.99/h
Nebius
H200 141 GB
8x H200
1 or 8
InfiniBand 400 Gbps
Finland, France
$5.40/h
OVHcloud
H200 141 GB
h200-1920
8
NVLink
France
€5.25/h
Crusoe
H200 141 GB
h200-141gb-sxm-ib.8x
8
InfiniBand 3.2 Tbps
Iceland
$4.29/h
Taiga Cloud
H200 141 GB
H200 SXM
8
Europe
from $3.50/h
AWS
H100 80 GB
p5.48xlarge
1 or 8
NVLink, EFA 3.2 Tbps
Stockholm, London, US
$6.88/h
Google Cloud
H100 80 GB
a3-highgpu-8g
1 to 8
NVLink
Netherlands, Belgium, Germany
$11.06/h
Verda
H100 80 GB
H100 SXM5
1 to 8
Finland
$4.89/h
Lambda
H100 80 GB
H100 SXM
1 to 8
NVLink
US
from $3.99/h
Crusoe
H100 80 GB
h100-80gb-sxm-ib.8x
8
InfiniBand 3.2 Tbps
Iceland, US
$3.90/h
Hyperstack
H100 80 GB
n3-H100-SXM5x8
8
SXM5
Canada, US
$3.20/h
Scaleway
H100 80 GB
H100-SXM-8-80G
2 to 8
SXM
Paris
€3.17/h
OVHcloud
H100 80 GB
h100-1520
1 to 4
France
€2.80/h
Denvr
H100 80 GB
H100 SXM
8
InfiniBand 3.2 Tbps
US, Canada
$2.45/h
Hetzner
RTX PRO 6000 96 GB
GEX131
1
Falkenstein, Helsinki
from €1,499/month
Hetzner
RTX PRO 6000 96 GB
GEX430
4
Helsinki
€3,599/month per server
Google Cloud
RTX PRO 6000 96 GB
g4-standard-48
1 to 8
PCIe Gen5
6 EU regions
$4.50/h
Exoscale
RTX PRO 6000 96 GB
RTX PRO 6000
1 to 8
Frankfurt, Vienna, Zurich, Zagreb
from €2.00/h
AWS
L40S 48 GB
g6e.xlarge
1 to 8
PCIe
Frankfurt, Stockholm, Spain
$2.33/h (Frankfurt)
OVHcloud
L40S 48 GB
l40s-90
1 to 4
France
€1.40/h
Scaleway
L40S 48 GB
L40S-1-48G
1 to 8
Paris, Warsaw
€1.47/h
Google Cloud
L4 24 GB
g2-standard-4
1 to 8
PCIe Gen4
5 EU regions
$0.71/h
AWS
L4 24 GB
g6.xlarge
1 to 8
PCIe
Frankfurt, Paris, Zurich and 3 more
$1.01/h (Frankfurt)
OVHcloud
L4 24 GB
l4-90
1 to 4
France
€0.75/h
Public on-demand list prices from each provider’s own pricing page or API, checked on 4 November 2026, per GPU unless stated. Prices exclude VAT, vary by region, and change often. AWS prices are for US East. You pay providers directly at these prices, with no Cloudfleet markup. Newest rack-scale systems such as GB200 and GB300 NVL72 are sold through reservations and capacity blocks rather than on demand. NVIDIA, HGX, Blackwell and the GPU model names are trademarks of NVIDIA Corporation.
Your entire infrastructure footprint. One unified cluster.
Managed control plane
Cloudfleet is CNCF-conformant, allowing seamless migration of any conformant clusters while avoiding vendor lock-in.
Node autoprovisioning
Cloudfleet dynamically provisions compute capacity based on real-time demand.
On-premises tooling
Add on-premises nodes to your cluster with a single command and schedule pods across both on-premises and cloud nodes.
Global networking
Nodes securely connect via an encrypted network spanning multiple clouds and regions.
Why GPU teams choose Cloudfleet
One Kubernetes cluster for every GPU you can get
The GPU shortage is not a pricing problem, it is a capacity problem. Your cloud has no H100s in the region you need, quota requests sit in a queue, and the provider that does have capacity runs a different stack. Meanwhile developers wait for resources while expensive GPUs sit idle in another account.
Cloudfleet turns scattered GPU capacity into one managed Kubernetes cluster. Add GPU nodes from any cloud, neocloud, or your own data center, and schedule workloads with standard Kubernetes. Cloudfleet installs the NVIDIA drivers and Container Toolkit, provisions GPU nodes when workloads need them, and removes them when they do not.
Capacity from every provider in one cluster
When one provider runs out, the next one has capacity. Run AWS, Google Cloud, Azure, Hetzner, OVHcloud, Scaleway, Lambda, Nebius and on-premises GPU servers in a single cluster, connected over an encrypted WireGuard® network. Your workloads follow the GPUs, not the other way around.
Every accelerator, side by side
Mix NVIDIA GPUs, Google TPUs, and AWS Trainium and Inferentia chips in the same Kubernetes cluster. Our catalog tracks 1,300+ instance types with their accelerator specs, so a node selector like cfke.io/accelerator-name: H100 gets you the most cost-effective match across clouds.
GPUs that never sit idle
Node auto-provisioning creates GPU nodes when a Pod requests nvidia.com/gpu and removes them when the job ends. Time slicing and Multi-Process Service (MPS) let several inference workloads share one GPU. You pay for GPU time you use, not for capacity you parked.
Your data, your jurisdiction
Training data and model weights stay on the GPU nodes you choose, such as EU providers like Hetzner, OVHcloud, Scaleway, and Exoscale, or your own servers. Cluster metadata stays encrypted in the Frankfurt control plane region, keeping both data and metadata within European jurisdiction.
Kubernetes manifest example
Request a GPU model, not a cloud
This Pod asks for one NVIDIA H100. If no node has a free H100, Cloudfleet provisions the most cost-effective H100 node across your cloud accounts. Add the cfke.io/provider label to pin a provider.
Cloudfleet CLI
Add an on-premises GPU server
Bring your own GPU servers into the same cluster. The flag installs and configures the NVIDIA drivers and the NVIDIA Container Toolkit.
This Pod asks for one NVIDIA H100. If no node has a free H100, Cloudfleet provisions the most cost-effective H100 node across your cloud accounts. Add the cfke.io/provider label to pin a provider.
Cloudfleet CLI
Add an on-premises GPU server
Bring your own GPU servers into the same cluster. The flag installs and configures the NVIDIA drivers and the NVIDIA Container Toolkit.
GPU procurement
We find the GPUs. You run the workloads.
On-demand GPUs are the tip of the market. Most H100, H200, B200 and B300 capacity is sold as reservations, capacity blocks, and committed contracts that never show up on a pricing page. Cloudfleet works closely with most infrastructure providers. Our team sources that capacity for you, helps you find the right deal, and connects the nodes to your cluster the day they are delivered.
GPU model and count, interconnect such as NVLink or InfiniBand, term, location, and start date. One request reaches every provider we work with, from hyperscalers to European GPU clouds.
Compare real offers
We come back with concrete options: on-demand, reserved, or committed, in the regions you need, including EU-only capacity for sovereign workloads. You pick the offer, and you contract and pay the provider directly.
Ready the day it lands
Reserved nodes join your Cloudfleet cluster as soon as the provider hands them over. No new stack to learn per provider, no separate cluster per reservation. Your workloads schedule onto the new GPUs with the manifests you already have.
Burst on demand, commit for the base
Run your steady training and inference load on reserved capacity, and let node auto-provisioning add on-demand GPUs from your cloud accounts when demand spikes. One cluster, one bill per provider, no idle reservations.
NVIDIA
Aligned with NVIDIA Enterprise Reference Architectures
NVIDIA Enterprise Reference Architectures describe how to build AI factories on open-source Kubernetes, from HGX 8-GPU nodes to the NVIDIA software stack that runs on them. Cloudfleet follows the same design: standard Kubernetes, NVIDIA drivers and Container Toolkit installed on every GPU node, and room for the NVIDIA operators and software your teams use.
Reference node designs
Run HGX nodes with 8 GPUs, NVLink, and high-speed networking such as InfiniBand or RoCE from cloud providers, or build reference-design servers in your own data center and add them to the cluster.
The NVIDIA software stack
Cloudfleet installs the NVIDIA drivers and Container Toolkit for you. Deploy the NVIDIA GPU Operator, Network Operator, NIM Operator, DCGM monitoring and Run:ai on top, with standard Kubernetes APIs and no proprietary layer in between.
GPU sharing built in
Turn on time slicing or MPS per cluster to share GPUs between inference workloads, and use the cfke.io/accelerator-name and cfke.io/accelerator-memory labels to place each job on the right GPU.
Training and inference in one cluster
Run distributed training on 8-GPU NVLink nodes, and serve models on L4, L40S, or RTX PRO 6000 nodes next to them. Same cluster, same manifests, same monitoring, from the first experiment to production traffic.
For NVIDIA Inception members
Migration Acceleration Program for fellow Inception startups
Cloudfleet is a member of NVIDIA Inception, and we know what building an AI startup on scarce GPUs feels like. Inception members get priority access to our Migration Acceleration Program: credits, Kubernetes architects, and hands-on help to move GPU workloads onto Cloudfleet and keep them running while you scale.
Offset cluster management fees, training and enablement, and professional services while you move your GPU workloads to Cloudfleet.
Kubernetes architects on your team
Cloudfleet Kubernetes architects plan your GPU cluster with you: node types, scheduling, GPU sharing, and the path from one provider to many.
Help finding the right GPUs
Our relationships with infrastructure providers work for you. We help Inception members find capacity and negotiate the right deal for their stage, from a few on-demand GPUs to reserved clusters.
Hands-on migration
Professional services move existing workloads from VMs, Slurm, or another Kubernetes platform with minimal disruption, so your team keeps shipping models during the move.
Get started
Get GPUs into a Kubernetes cluster this week
Create a GPU cluster
Start with $230 (€200) in credit. Connect your cloud accounts, request a GPU in a Pod spec, and Cloudfleet provisions the node.
Tell us which GPUs you need, how many, where, and for how long. We use our provider relationships to find the right deal and connect the capacity to your cluster.
Any NVIDIA GPU your providers offer, from L4 and L40S for inference to H100, H200, B200 and B300 for training. GPU nodes from AWS, Google Cloud, Azure, Hetzner, OVHcloud, Scaleway, Lambda, Nebius, Exoscale and your own data center join the same cluster through node auto-provisioning, the Cloudfleet API, or Terraform. Google TPUs and AWS Trainium and Inferentia run in the same cluster as well. For the newest GPUs, see where to rent NVIDIA B300.
You tell us the GPU model, quantity, interconnect, term, location and start date. Cloudfleet works closely with most infrastructure providers, so our team collects offers for you, including reserved and committed capacity that is not listed publicly, and helps you choose. You contract with and pay the provider directly, and the nodes join your Cloudfleet cluster when they are delivered. See GPU procurement in a shortage for how on-demand, reserved, and committed capacity compare.
No. Your cloud provider bills you directly for GPU nodes at its own prices. Cloudfleet charges a cluster management fee, starting at $14/month (€12) on Basic and $79/month (€69) on Pro with a 99.95% SLA, and every new account gets $230 (€200) in credit.
No, but we work closely with most infrastructure providers, and we are happy to help you with procurement and finding the right deal. On the technical side, Cloudfleet does far more than a marketplace. It manages your entire cluster: the control plane, node auto-provisioning across providers, NVIDIA drivers and Container Toolkit, encrypted networking between locations, GPU sharing, and Kubernetes upgrades. You get GPUs and a production-ready platform to run them on. See GPU marketplace vs managed GPU Kubernetes for the difference.
NVIDIA’s Enterprise Reference Architectures build AI factories on open-source Kubernetes with HGX nodes, high-speed networking, and NVIDIA software such as the GPU Operator, Network Operator, and Run:ai. Cloudfleet follows that design with standard Kubernetes, NVIDIA drivers and Container Toolkit on every GPU node, and full support for NVIDIA operators. Read NVIDIA Enterprise Reference Architectures for Kubernetes teams for how the pieces fit.
Yes. Cloudfleet is a member of NVIDIA Inception, and fellow Inception startups get priority access to our Migration Acceleration Program: up to $10,000 in credits, Cloudfleet Kubernetes architects, help finding GPU capacity, and hands-on migration support. Talk to an expert to apply.
Yes, within each provider’s high-speed fabric. Schedule distributed training jobs onto the 8-GPU nodes of one provider and region, where NVLink and InfiniBand or EFA connect the GPUs, and use other providers for inference, fine-tuning, and burst capacity in the same cluster.
Yes. Time slicing and Multi-Process Service (MPS) let several Pods share one GPU, which suits inference and development workloads. GPU sharing is a cluster-level setting on the Pro and Enterprise tiers. See training and inference in one cluster for how to combine whole-GPU training with shared inference.
On the GPU nodes you choose. Cloudfleet never holds your application data. Choose EU providers or your own servers for the nodes, and the Frankfurt control plane region keeps cluster metadata encrypted in Germany, so both data and metadata stay within European jurisdiction.
Cloudfleet seamlessly extends your cluster anywhere, turning any hardware - even in your office or home - into a modern enterprise cluster.
Jules Huls
Information Security Expert
Using Cloudfleet together with Hetzner allowed us to bring up a managed Kubernetes cluster just as quick as with any US-based hyper-scaler, but with the benefit of being EU hosted which is very valuable in today's times.
Martin Schulze
CEO & Founder
By combining our standardized configurations with the powerful automation features of the Cloudfleet platform, we've built a development workflow that is fast, secure, and incredibly efficient.
Onur Solmaz
VP of Engineering and Research
Perfect balance between flexibility and managed service - and the support is outstanding.
Daniel Costa
Sales Engineer
We deploy to customer infrastructure without changing how we build or manage Kubernetes.
Julian Becker
Principal DevOps Engineer
It is easy to build a multi-cloud setup without getting locked into any single provider.
Carlos Mendes
Infrastructure Architect
It is easy to build a multi-cloud setup without vendor lock-in.
Luca Meyer
Principal DevOps Engineer
Cloudfleet lets us scale our game servers across multiple providers - reliably and affordably.
Max Keller
Senior DevOps Engineer
Cloudfleet not only cut our infrastructure costs - it saved us hours of work by taking cluster management off our plate.
Richard Callahan
Engineering Manager
Why Cloudfleet
Designed for modern cloud operations.
Hybrid-cloud by design
Run Kubernetes consistently across public cloud, private infrastructure, and on-prem environments, with a single control plane and unified operational model.
Operational simplicity
Operate, scale, and migrate Kubernetes clusters across environments using a consistent, opinionated platform that reduces operational overhead.
Predictable costs
Transparent pricing and infrastructure control help you avoid hyperscaler lock-in, hidden fees, and unexpected cost growth as your workloads scale.
No vendor lock-in
Retain full portability of your clusters, workloads, and tooling by running standard Kubernetes without proprietary extensions or forced dependencies.
Production-grade support
Designed for production workloads, with operational tooling, escalation paths, and support processes built to meet enterprise reliability requirements.
Enterprise-ready security
Secure by default, with isolation, encryption, and access controls designed to meet the requirements of regulated and security-conscious organizations.
Try Cloudfleet with €200 in credit
Create a managed Kubernetes cluster in minutes. Every new account gets €200 in credit, so you can explore the full platform with no charge until it's used or expires.